What you get
A 512×512 picture, 20 steps, on one eight-year-old graphics card that normally cannot run this software at all. Before: five minutes and twenty-five seconds. Now: one minute and eighteen seconds. Same card, same model, same code — different instructions inside it.
And it draws the same watts for a quarter of the time
A GPU does not get cheaper by being clever — it gets cheaper by finishing sooner. The card is pegged at full load for the whole render either way, so wall-clock time and electricity are the same quantity. Energy is power × time, and only the time changed.
The assumption, stated rather than hidden. Power was not logged during the slow build. The figures below use the load draw already measured by the Nim Power Meter on this machine — about 11 W idle, 318 W at full load — and hold it constant. If the slower build drew less (poor occupancy can leave a GPU under-fed), the saving shrinks. The table shows how much:
| If the slow build drew | Wh per image, before | Wh saved per image | Energy ratio |
|---|---|---|---|
| 200 W | 18.1 | 11.6 | 2.8× |
| 250 W | 22.6 | 16.1 | 3.5× |
| 300 W (headline) | 27.1 | 20.6 | 4.2× |
Even the least flattering row is a 2.8× cut in electricity per picture. The time ratio (4.19×) is exact; only the power ratio is assumed.
Put in units you can act on: a hundred 512×512 renders went from 2.7 kWh to 0.65 kWh — about the difference between running a space heater for two hours and running it for half an hour, for identical output.
It did not just get faster — it started working
For a while every picture came out as a perfectly flat white rectangle. Not a bad picture. A blank one: one single colour, 8,746 bytes of file. That is the fingerprint of a number that has gone to infinity and been clipped on the way out.
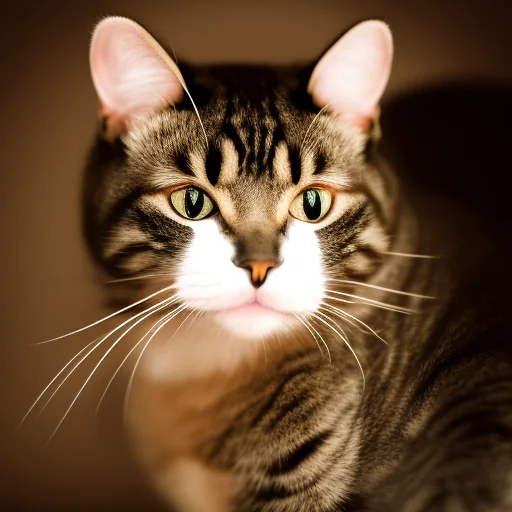
The strongest proof we have: the cat picture after the fix is byte-for-byte identical to the picture produced before things broke (md5 1588f0f1…). Not "looks similar" — identical. A faster renderer that quietly changes the output is a bug; this one does not.
Every number in this report comes from sd-rx580/evidence/bench.csv and is reproducible with sd-rx580/tools/bench.sh. Nothing here is estimated.
Why a graphics card is a rowing boat
A GPU does not run one instruction at a time. It runs them in fixed-size squads, and every member of the squad must move together — like a rowing crew in one boat. When the squad is told "everyone grab the fourth item", all 32 or all 64 rowers do it at once.
The catch: how many rowers are in the boat is a property of the hardware. Apple's own chips put 32 in a boat. This AMD RX 580 puts 64 in the boat. Software written by counting on 32 gets two possible endings:
- The wasteful one. It only ever calls 32 rowers. Half the boat sits idle, doing nothing, for the entire race.
- The dangerous one. It does the arithmetic for seat n assuming seats stop at 31. At seat 48 it asks for something that does not exist, and reads whatever happens to be next in memory.
Where the bug actually came from
The port had been told, in so many words, "pretend the boat has 32 seats". That works — the crew rows in half the boat and the numbers come out right. Unfortunately the other half of the code still believed it had 64 seats, and the two disagreed. The disagreement produced infinities, and infinity clipped to white.
So the first fix was not an optimisation. It was removing a lie: tell the software how many seats the boat really has. The white pictures disappeared, and the cat came back byte-identical to the older working build.
And that is not the whole story either. Fixing the seat count restored correctness. It barely touched speed — 20.8 to 19.7 seconds per step. The speed came from somewhere else entirely, and Part 3 shows how we found it.
Does this matter beyond one old card?
Yes, and this is the part worth sending to anyone who thinks 64-lane hardware is ancient history.
64-lane hardware is the current frontier
AMD's data-centre line — MI100, MI200, and MI300 — runs 64-wide waves as its native mode. The same is true across the CDNA family. A habit of "assume 32" is not a legacy problem; it is a problem that lands on the most expensive accelerators you can buy.
Consumer RDNA (RX 5000 and later) prefers 32 but still supports 64.
And it is already shipping to real users
Every Intel-era Mac with a GCN AMD GPU — Polaris, like this RX 580, and Vega — reports a 64-wide wave through Metal. Anyone running local AI on one of those machines is on this path today, with no alternative graphics API. RDNA Macs report a different width and we did not verify them: the 2026 reports show they fail in their own way, not that they are immune.
That is a large, quiet population, not a laboratory curiosity.
Our honest limitation. There was exactly one GPU available to test on: an RX 580 (Polaris, gfx803). We could not validate on MI300, on RDNA, or on a second AMD Metal device. What we can say is that the pattern — derive the lane maths from the hardware, never write 32 — is what makes a kernel survive on any of them. Part 4 turns that into a concrete patch for llama.cpp.
Four bugs, in the order they were found
Each one was found by measurement, not by reading code and guessing. The order matters, because three of the four were invisible until the previous one was gone.
Bug 1 — the lie about the boat size
A width-32 clamp, added in two places. Symptom: pure white images, std exactly 0.00. The proof was a clean A/B — an older binary in the tree reported simdgroup width = 64 and rendered correctly; the newer one reported 32 and did not.
How we proved it was not the kernels: pointing the backend at the older kernel snapshot changed nothing; running the text encoder on CPU changed nothing; running the VAE decoder on CPU changed nothing. All three produced byte-identical white pixels, so the output was constant and the fault had to be in the C++.
Bug 2 — a number doing two jobs
Once images were correct, the conformance matrix showed the compressed weight formats — the ones squeezed into fewer bits to save memory — were badly wrong: 36 pass / 39 fail for q8_0, 37 / 43 for q4_0. The cause was one constant, NQ, being used for two unrelated things: how many weights one lane handles, and how many blocks the squad advances per round. At 32 seats those two numbers happen to be the same. At 64 they are not, and half the lanes read past the end of their block.
Splitting it into "lanes per block" and "blocks per round" fixed all four formats at once.
Bug 3 — the optimiser that never ran
This is the one that mattered most, and it hid for two hours.
We had written a tiled matrix multiplier — the thing that makes GPUs fast — and measured a solid 2× improvement. Then three more improvements each returned about 1%, which looked like a hardware ceiling. It was not. It was a ceiling on 30% of the work.
The fix to the measurement tool was trivial and embarrassing: a timing print that fired only on every 32nd event, when a single image produces far fewer than 32 events. Once it printed every time, the answer took ten seconds to read:
| Part of one image | Time on GPU | Verdict |
|---|---|---|
| Text encoder (CLIP) | 0.06 s | irrelevant |
| Image generator (UNet), per step | 6.05 s | 80% of the run |
| Image decoder (VAE), one graph | 24.6 s | 16% — in one place! |
And the tiled multiplier had a guard: only for 32-bit float data. The convolutions — the entire decoder, and every convolution inside the generator — run in 16-bit data. They never used it. We had been optimising the part that was already fast.
Teaching the tiled kernel about 16-bit data halved the generator (6.05 → 3.26 s per step) and cut the decoder from 24.6 s to 16.1 s. That single change was worth more than everything before it.
Bug 4 — the obvious answer that lost
With a working tiled kernel, the obvious next step was a bigger tile: 32×32 instead of 16×16. It should have won, because a bigger tile reads the weights fewer times. It lost by 18%.
The reason is the same rowing boat. A 32×32 tile at one output per thread needs a crew of 1024. On this card that leaves room for barely two crews per engine, so there is almost nothing in flight to hide the memory delays. The fix was not a bigger crew — it was the same 32×32 tile held in registers, on a crew of 256. Same reuse, four times the concurrency. That is the last 13%.
The instrument that made this possible
None of the above was found by staring at code. It was found by a small test bench that runs the vendor's own conformance suite once per data format and prints a pass/fail matrix:
| Weight format | Failures before | Failures after | Used by SD 2.1? |
|---|---|---|---|
| f32 | 150 † | 0 | yes — most of it |
| f16 | 186 † | 0 | yes — convolutions |
| q8_0 | 39 | 0 | optional |
| q4_0 | 43 | 0 | optional |
| q4_1 · q5_0 · q5_1 | not measured | 0 | optional |
| q5_K · q6_K | not measured | 0 | optional |
| q2_K · q3_K · q4_K · mxfp4 | not measured | 9 · 41 · 17 · 17 | no |
† Those two "before" figures come from the wider unfiltered run taken before the fixes — the plain-path filter used for every other number here did not exist yet, so they are indicative, not like-for-like. q4_0 and q8_0 are exact before/after on identical filters.
The bottom row is the honest part: four exotic formats are still wrong. They are listed, not hidden, and they do not affect Stable Diffusion because it never uses them. Every known failure is consolidated at the back →
A measurement lesson worth more than the speedup. We re-ran the identical kernel, producing byte-identical images, three times: 89.1 s, 89.6 s, 92.7 s. That is 4% run-to-run noise. Every "1% improvement" before we knew that was noise being mistaken for progress. The real wins were 13%, 43% and 110% — comfortably outside it.
We kept hitting the same bug in llama.cpp — so this is where we finally corner it
Everything above lives in a fork of stable-diffusion.cpp, which shares its compute layer with llama.cpp. That is not a coincidence we noticed afterwards. Running llama.cpp on this card kept producing the same wrong answers, across several attempts, and nothing we tried cleared it.
A diffusion pipeline was simply the easier place to catch the culprit: when the maths goes wrong there you get a visibly wrong picture, not a plausible-looking sentence. Chapter 1 is that capture. This chapter takes the same defect back to where it lives.
The series
Chapter 1 — this page. Stable Diffusion 2.1 on an RX 580: the white
images, the four bugs, 4.19× faster. Finished, measured, reproducible.
Chapter 2 — next. llama.cpp on 64-lane hardware: reproduce the failure on
a stock build, apply the patch below, carry it upstream. The patch already exists; what
remains is switching those four jobs back on and running them this page does not claim.
kernels/common.h:24
  #define N_SIMDWIDTH 32   // default; ggml_metal_device overrides it with the real width

ggml-metal-device.m:470
  if (simd_width > 0 && simd_width != 32) {
      [prep setObject:... forKey:@"N_SIMDWIDTH"];   // adopts the real width
  }

kernels/mul_mv.metal:259
  const short ix = (tiisg/(NW/NQ));
  const short il = (tiisg%(NW/NQ))*8;              // NW = N_SIMDWIDTH
Read those three lines together in plain terms. The card tells the software how many rowers are in the boat, and the software listens — good. But then it decides which part of a box to fetch by dividing the seat number, and with 64 seats that division hands out positions the box does not contain.
Weights live in small boxes of 32 numbers. Two rowers finish a box: sixteen numbers each. The code assumed four rowers would share it — which is only true when the boat has 32 seats. With 64 seats, two of every four rowers reach past the end of their box and pick up whatever is lying next to it in memory. Nothing crashes. The arithmetic still runs. The answer is just quietly wrong.
And the llama.cpp project already knows. This is where I was wrong the first time. I expected to find something nobody had noticed. What is actually there is a list — a list of jobs the card is allowed to do — with a note written beside it:
static bool ggml_metal_supports_mul_mat_wide(...) {
    // q4_0/q4_1/q5_0/q5_1 still route through mul_mv_ext, which is not yet correct at 64
    // lanes (0/121, 0/99, 0/63, 0/56 on MUL_MAT) even with nypsg and the dispatch width
    // fixed - keep them on the CPU path until that is resolved.
    case GGML_TYPE_Q4_K: ...
Read that note as a sentence, because that is what it is: these four are not right on 64-seat cards yet, so we keep them off the card until someone fixes it. Somebody found the same thing, measured it, wrote the numbers down, and switched the job off. With the job switched off, the slow brain does the work instead — which is why this shows up as slowness rather than as wrong answers.
I checked that on this machine with the project's own test program: every one of those cases comes back "not supported", and nothing runs. Not broken — declined.
Which makes the contribution smaller and more useful than "I found a bug". The note ends with until that is resolved. This is the resolve.
How long has this been open?
Longer than a bug this simple should survive — and mostly because each report landed as an isolated mystery instead of one named defect.
| When | What happened |
|---|---|
| Sep 2023 | llama.cpp #3000 — "[macos] AMD GPU using mul_mm in metal". The first report we can find. Closed automatically as stale after 14 days of inactivity. |
| Jun 2024 | ollama #5071 — "not utilizing AMD GPU through METAL". The same fault, reported from the application layer instead of the backend. |
| Feb 2026 | #19563 — "Metal backend produces garbage output on AMD discrete GPUs". The blank-image class of failure, reported plainly. |
| Feb 2026 | #19601 — two distinct bugs named: concurrent dispatch broken on non-UMA, and simd_max(half) wrong with −INF on RDNA. Both fixed on the reporter's branch. |
| Jun 2026 | MoltenVK #2756 — the same 64-wide subgroup assumption breaks Vulkan-on-Metal shuffle ops on RDNA. A different project, the same root cause. |
So: reported in 2023, closed as stale, rediscovered in 2026. Three years is not because the fix is hard — it is three small edits — but because nobody owned the problem long enough to reproduce it twice.
Credit where it is due: our fork already carries the first two fixes from #19601 — concurrency disabled when the GPU has no unified memory, and the simd_max half→float cast. That work is why this card renders at all. The third item is different in kind: q4_0/q4_1/q5_0/q5_1 are not broken by accident. They are excluded on purpose, in a comment that asks for exactly this fix.
What is proven, and what is still owed. Proven here: the mistake is real and measured — 43 of those cases failed on this card before the fix, none after. Proven about the project: with their list unchanged, those four jobs never reach the card at all. Still owed: cross the four lines off that list, apply the patch, and run it. Their own note says the count is zero out of 121 today. The patch should make it 121 out of 121. Until somebody runs it, that is an expectation, not a result.
The patch, in three ideas
// 1. Derive "lanes per block" from the block, never from the wave width.
constexpr short NLB = QK4_0/NQ;   // 32 quants / 16 per lane = 2 lanes per block
constexpr short NBL = NW/NLB;     // blocks advanced per round: 16 at 32 lanes, 32 at 64
const short ix = tiisg/NLB;
const short il = (tiisg%NLB)*8;

// 2. Advance by the number of blocks actually covered per round.
for (int ib = ib0; ib < nb; ib += NBL) { ... yb += QK4_0*NBL; }

// 3. Same treatment for q8_0, which has the identical "NQ does two jobs" defect.
At 32 lanes these reduce to exactly the current expressions, so Apple Silicon cannot regress — that is the property that makes the patch reviewable.
The performance half
The same card was also slow, for an unrelated reason. When the graphics chip has no built-in shortcut for multiplying tables of numbers — and this one does not — the software falls back to a method that re-reads the entire weight table once for every single output column. That is like re-reading the whole recipe before cutting each individual slice of cake.
The fix is the obvious one in kitchen terms: read the recipe once, then cut a whole tray of slices from that one reading. In this card's case that alone was worth more than doubling the speed. The engineering detail is in llama-cpp/ALGORITHM.md for anyone who wants it.
How to check it yourself
# On any device where threadExecutionWidth != 32:
./build/bin/test-backend-ops -b MTL0 -o MUL_MAT -p type_a=q4_0
./build/bin/test-backend-ops -b MTL0 -o MUL_MAT -p type_a=q8_0

# Note: -p splits on commas into key=value pairs, so shape filters such as
# bs=[1,1] cannot be expressed there - filter the printed case strings instead.
# Export GGML_METAL_PATH_RESOURCES to the source tree, or the backend compiles a
# stale copy of the kernels from build/bin/kernels and your edit does nothing.
Patch, facts and adoption notes: wave64-report/llama-cpp/. Deliberately no PR draft — llama.cpp prohibits AI-written PR descriptions, so the submission has to be written by the person who did the work.
The details, without the kitchen words
Where the code lives
| Thing | Path |
|---|---|
| The port | sd-rx580/Vendor/stable-diffusion.cpp/ggml/src/ggml-metal/ |
| The patch | sd-cpp/ — how to apply, with the ggml diff (24 files) and the ggml_extend diff |
| Tiled GEMM | kernels/mul_mv.metal — kernel_mul_mm_simt_{f32,f16,f16_f16,f32_f16} |
| Dispatch | ggml-metal-ops.cpp — branch before ggml_metal_op_mul_mat_mv |
| Conformance matrix | sd-rx580/tools/matrix.py |
| Benchmark | sd-rx580/tools/bench.sh → evidence/bench.csv |
| Hardware probe | sd-rx580/tools/wave_probe.mm |
| The board | sd-rx580/docs/wave64-board.md |
Reproduce it
cd sd-rx580/Vendor/stable-diffusion.cpp
cmake --build build --target sd-cli test-backend-ops -j8   # skip the .air targets:
                                                          # xcrun metal is not installed

cd ../../tools
./wave_probe                       # dispatch-width semantics on this GPU
./matrix.py --plain f32 f16        # the gate: expect 0 fail
PROMPT="a photo of a cat" STEPS=20 SEED=42 ./bench.sh mytest   # s/it + image stats
Numbers as measured
| Config | 20-step total | s/it |
|---|---|---|
| matvec fallback | 325.1 s | 16.26 |
| tiled GEMM, f32 src1 | 155.6 s | 7.78 |
| tiled GEMM, all src1 | 89.1 s | 4.45 |
| 32×32 / 1024 threads | 107.3 s | 5.37 |
| 16×32 / 512 threads | 95.7 s | 4.78 |
| 32×32 register-blocked / 256 | 77.6 s | 3.88 |
Things that will waste your afternoon
- The kernel copy. Without GGML_METAL_PATH_RESOURCES, the backend compiles build/bin/kernels/*.metal — a build-time snapshot. Edits under ggml/src/ silently never reach the GPU.
- -p is not a regex. It splits on commas into key=value constraints, so bs=[1,1] becomes two broken tokens. Filter in Python instead.
- Shader compilation is not free. ~50–80 s per changed kernel source, per process. Batch your kernel edits.
- xcrun metal is missing without full Xcode, so the metallib targets fail. Build the binaries only.
- A gate that can never pass is not a gate. An unfiltered matrix is dominated by broadcast/permute shapes no diffusion model emits.
Known failures — kept deliberately
Everything below is still broken, still unmeasured, or still an assumption. It is gathered in one place, at the back, so it cannot be missed and no reader has to discover it alone.
| Item | State | Does it matter for SD 2.1? |
|---|---|---|
| q3_K quantised matvec | 41 of 41 fail | no — format unused |
| q4_K quantised matvec | 17 fail | no — format unused |
| q2_K quantised matvec | 9 fail | no — format unused |
| mxfp4 quantised matvec | 17 fail | no — format unused |
| Flash attention at width 64 | does not exist | yes — costs speed |
| Small-N matmuls (ne11 < 16) | still on the slow matvec path | yes — some |
| f32 / f16 "before" matrix figures | not like-for-like (†) | caveat only |
| q4_1 / q5_0 / q5_1 / q5_K / q6_K "before" | never measured | no |
| Electricity per image | derived from 300 W, not measured | caveat only |
| RDNA simdgroup width | unverified | no — this card is GCN |
| Upstream llama.cpp reproduction | outstanding | Chapter 2 |
Two of these deserve a sentence rather than a table cell.
Flash attention is the failure that costs you something. The port wraps every fa_vec_* instantiation in #if N_SIMDWIDTH == 32, so at width 64 the entire vector flash-attention family compiles out and the UNet falls back to explicit softmax. Porting those kernels is a prerequisite for flash attention to exist here at all — not a tuning knob to turn later.
The quantised formats nobody uses are still wrong. It would have been easy to delete four rows from a table and ship a report that looks complete. They stay because a matrix with holes in it, honestly labelled, is worth more than a green one that quietly omits its failures.
If something in this report is wrong, the most likely place is one of the eleven rows above.